Understanding Image Annotation Formats for Object Detection
A Beginner’s Guide to YOLO, COCO, Pascal VOC, and More
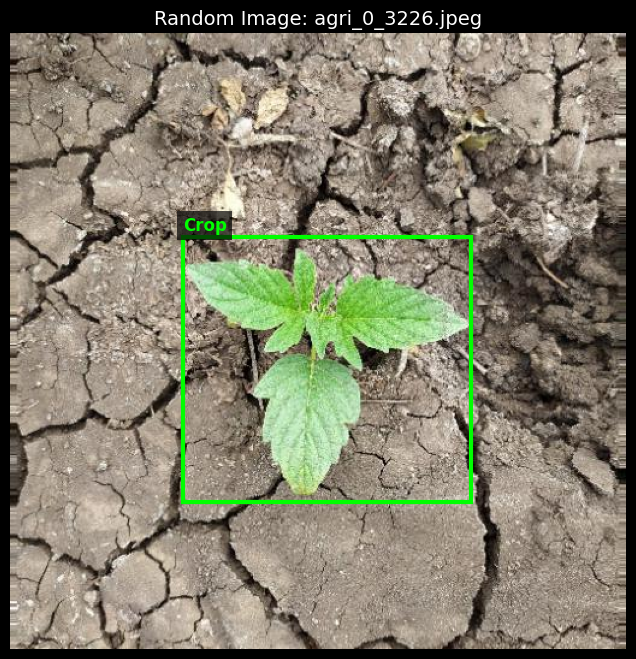
When working on computer vision projects, the choice of image data format is crucial. Different formats store image annotations in different ways, and picking the right one can make or break your workflow.
If you’re training a model to detect objects in images, understanding these formats will save you time and headaches.
Why Image Data Formats Matter
Imagine you have thousands of images of traffic signs. You want to train an object detection model to recognize stop signs, speed limits, and pedestrian crossings.
But before training, you need to tell your model where each object is. That’s where annotation formats come in.
Different datasets use different formats. Some store annotations as .txt files, others use .xml, .json, or even .csv. Each format has its pros and cons, depending on your project and the tool you’re using.
Common Image Annotation Formats
1. YOLO Format
YOLO (You Only Look Once) is one of the most popular object detection models, and it comes with a simple annotation format.
Annotations are stored in .txt files with the same name as the image.
Each line represents an object and contains:
Class ID (a number representing the object class)
Bounding box coordinates (x, y, width, height)
Values are normalized between 0 and 1.
Example (image1.txt):
0 0.5 0.5 0.2 0.3
1 0.7 0.8 0.1 0.2
This means:
Object of class 0 at the center (0.5, 0.5) with width 0.2 and height 0.3.
Object of class 1 at (0.7, 0.8) with a smaller bounding box.
Pros: Easy to read, lightweight, and works well with YOLO-based models. Cons: Doesn’t store labels or metadata in a structured way.
2. Pascal VOC Format
Used in the famous Pascal VOC dataset, this format relies on XML files.
Stores image details and multiple objects per file.
Each annotation includes:
Image name, size, and object list.
Bounding box (xmin, ymin, xmax, ymax).
Example (image1.xml):
<annotation>
  <filename>image1.jpg</filename>
  <size>
    <width>800</width>
    <height>600</height>
  </size>
  <object>
    <name>car</name>
    <bndbox>
      <xmin>100</xmin>
      <ymin>150</ymin>
      <xmax>300</xmax>
      <ymax>400</ymax>
    </bndbox>
  </object>
</annotation>Pros: Well-structured, easy to parse. Cons: XML format is bulkier than plain text.
3. COCO Format
COCO (Common Objects in Context) is a widely used dataset that uses JSON for annotations.
Stores multiple images in a single .json file.
Includes:
Image IDs, file names, and dimensions.
Object categories, bounding boxes, and segmentation masks.
Example (snippet from annotations.json):
{
  "images": [{"id": 1, "file_name": "image1.jpg", "width": 1024, "height": 768}],
  "annotations": [{"image_id": 1, "category_id": 2, "bbox": [200, 300, 150, 200]}]
}Pros: Ideal for large datasets, supports segmentation. Cons: More complex than YOLO or Pascal VOC.
4. CSV Format
Some datasets store annotations in a simple CSV file.
Each row corresponds to an object in an image.
Typically contains:
File name, class label, and bounding box coordinates.
Example (annotations.csv):
image1.jpg,car,100,150,300,400
image2.jpg,person,50,60,120,220Pros: Easy to use with Pandas. Cons: No standard structure, can vary between datasets.
Which Format Should You Use?
It depends on your project:
For YOLO models → Use YOLO format.
For TensorFlow and PyTorch projects → Pascal VOC or COCO.
For simpler applications → CSV works fine.
If you’re using tools like Roboflow, you can easily convert between formats.
Choosing the right image annotation format is essential for training a successful computer vision model.