Turn ideas into working apps with plain English - no code, Stripe ready.
Get startedFeature Extraction and Convolutional Neural Networks
Understanding the Core Mechanics Behind Object Detection

Object detection relies on identifying important patterns in images, a process known as feature extraction. Convolutional Neural Networks (CNNs) are the backbone of modern object detection systems because they excel at extracting these features. In this chapter, we will explore how CNNs work, their role in feature extraction, and why they are crucial for object detection.
What is Feature Extraction?
Feature extraction is the process of identifying important characteristics in an image that help distinguish objects. These characteristics include:
Edges – The outlines of objects
Textures – Patterns in the image, such as stripes or spots
Shapes – Geometric structures like circles or rectangles
A CNN extracts these features by applying mathematical operations to the image, detecting patterns at different levels.

Understanding Convolutional Neural Networks (CNNs)
A CNN is a type of deep learning model designed to process images efficiently. It consists of several layers, each with a specific purpose:
Convolutional Layers – Extract important features using filters (kernels).
Activation Function (ReLU) – Introduces non-linearity, allowing the network to learn complex patterns.
Pooling Layers – Reduce the size of feature maps, keeping only essential details.
Fully Connected Layers – Combine extracted features to make predictions.
Each layer refines the image representation, allowing the model to detect increasingly complex patterns.

How Convolution Works
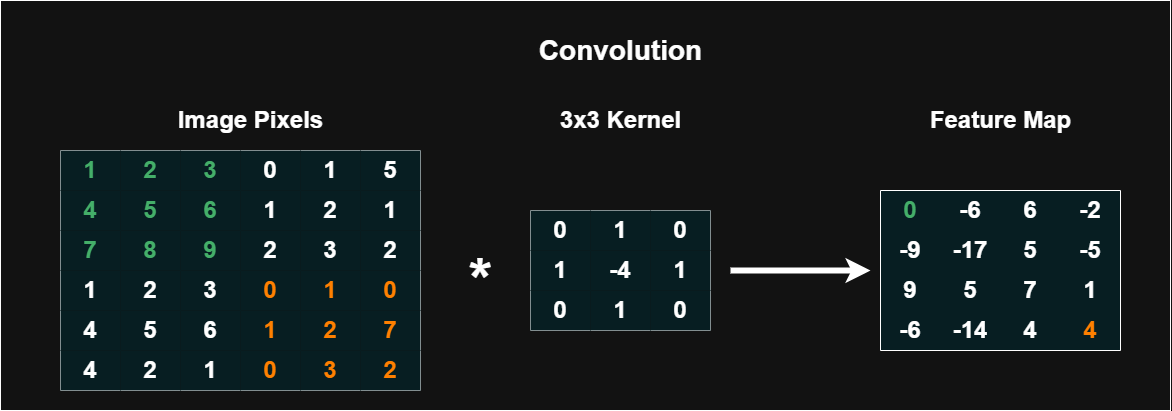
Convolution is a process where a small matrix (filter/kernel) slides over the input image to detect specific features.
Example of Convolution:
Imagine a 3x3 filter applied to an image. It multiplies pixel values in its region and sums them up to produce a new pixel value in the feature map. This helps in detecting edges, textures, or patterns.
Key properties of convolution:
Stride – The step size of the filter as it moves.
Padding – Adds extra pixels around the image to preserve size.
Activation Function: Making CNNs Smarter
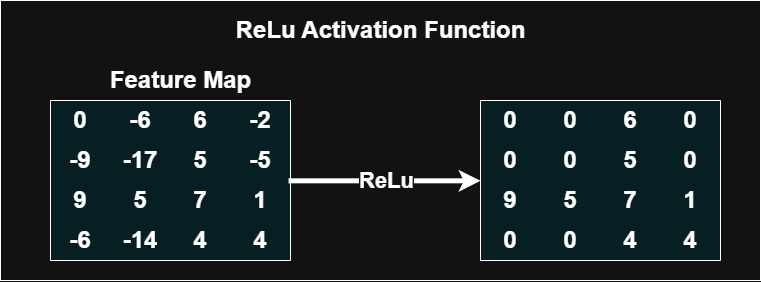
After convolution, we use an activation function called ReLU (Rectified Linear Unit). This function introduces non-linearity, allowing CNNs to detect more complex features.
ReLU works by:
Keeping positive values unchanged
Replacing negative values with zero
This helps prevent unwanted information from passing through the network.
Pooling: Reducing Complexity
Pooling is used to reduce the size of feature maps while keeping important information. It helps CNNs be more efficient and less sensitive to small variations in the image.
Two Types of Pooling:
Max Pooling – Selects the highest value in a region (helps in edge detection).
Average Pooling – Averages the values in a region (smooths out noise).

Fully Connected Layers: Making Predictions
After extracting features, the CNN flattens the feature maps into a 1D vector and passes them through fully connected layers. These layers:
Interpret extracted features
Assign probability scores to object categories
Output the final prediction
This is the last step before the CNN decides what an object is in an image.
Why CNNs Are Perfect for Object Detection
CNNs are ideal for object detection because they:
Detect features at different levels (edges, textures, shapes)
Recognize objects regardless of position or scale
Are efficient for processing large datasets
Modern object detection models like YOLO (You Only Look Once), SSD (Single Shot Detector), and Faster R-CNN all use CNNs for feature extraction.
Read More
Read more articles on the topics that interest you
Solar Cost for Small Businesses in South Africa: Ranges
See what different system sizes include, where extra costs hide, and how to compare quotes
How to Buy Bitcoin in South Africa Legally in 5 Steps
Choose a provider, pay in rand, check the costs and keep tax records
How to Build a Full-Stack Web App With AI in 7 Steps
Adapt a starter project, then use AI to build, test and launch your first working version
Best AI Website Builders for Beginners in 2026: 5 Picks
Compare easy site creation, online selling, costs and the trade-offs before you choose
6 Ways South African Youth Can Fight AI Unemployment
Build skills employers need, earn while learning and make AI work alongside you
Jobs most likely to be replaced by Artificial Intelligence
Exploring careers at risk due to AI advancements and automation