Turn ideas into working apps with plain English - no code, Stripe ready.
Get startedTraining a Convolutional Neural Network for Object Detection: Number Plate Detection
Teaching Machines to Spot and Frame Number Plates in Images

Introduction to Bounding Box Detection
Object detection is a crucial task in computer vision that enables machines to not only recognize objects within an image but also determine their exact locations. This capability is essential in applications such as autonomous driving, surveillance, and smart traffic monitoring. In this article, we focus on the task of detecting vehicle number plates using deep learning, where our objective is to train a Convolutional Neural Network (CNN) that can accurately localize number plates in images.
This problem falls under the category of bounding box regression, where the model learns to predict the location of an object in an image using a rectangular bounding box. To accomplish this, we will process a YOLO-format dataset, train a CNN from scratch, and evaluate its performance using real-world images of vehicles.
Why Number Plate Detection Matters
Automatic Number Plate Recognition (ANPR) is widely used for:
Traffic Monitoring & Law Enforcement: Cameras installed on roads use object detection models to track vehicles and enforce traffic regulations.
Parking Systems: Automated parking systems rely on ANPR to recognize vehicles and manage access control.
Toll Collection: Many modern toll systems identify and charge vehicles automatically using number plate detection.
Security & Surveillance: Number plate detection is vital in tracking stolen vehicles and enhancing public safety.
To achieve high accuracy and real-time performance, we need an efficient CNN-based object detection model that can generalize well across different environments, lighting conditions, and camera angles.
Classification vs. Object Detection
Before diving into number plate detection, it’s important to distinguish it from image classification.
1. Image Classification
Image classification involves assigning a category label to an entire image. For example, a classification model trained on traffic images might categorize an image as containing a "vehicle" or "pedestrian." However, classification alone does not provide the location of the object—it only tells us what is in the image, not where.

2. Object Detection
Object detection, on the other hand, goes a step further. It identifies multiple objects within an image and determines their locations by drawing bounding boxes around them. In the context of number plate detection, an object detection model would:
Detect the number plate in an image containing a vehicle.
Predict the bounding box coordinates of the number plate.
For example, if a car is captured in an image, a well-trained model should be able to locate the number plate, outline it with a rectangular box, and return its coordinates.

Understanding Bounding Boxes in Object Detection
A bounding box is a rectangular region that defines the position of an object in an image. In YOLO-format datasets, bounding boxes are represented using normalized coordinates, which means all values are scaled between 0 and 1 relative to the image dimensions. Each bounding box is described using:
center_x– The normalized x-coordinate of the bounding box center.center_y– The normalized y-coordinate of the bounding box center.width– The normalized width of the bounding box.height– The normalized height of the bounding box.

For instance, if a number plate is positioned in the middle of an image, its bounding box might be represented as:
<object_class> <center_x> <center_y> <width> <height> Where:
<object_class>represents the object class (e.g., "0" for number plates).<center_x>, <center_y>, <width>, <height>are floating-point values between 0 and 1.
Example annotation for a number plate:
0 0.52 0.65 0.30 0.12 This indicates that the number plate's center is located at (0.52, 0.65), and its bounding box has a width of 0.30 and height of 0.12 relative to the image size.
Alternative Bounding Box Representations
While the YOLO format uses normalized coordinates (center_x, center_y, width, height), other object detection frameworks represent bounding boxes differently. Some common formats include:
Pascal VOC Format
(xmin, ymin, xmax, ymax)Uses absolute pixel coordinates.
(xmin, ymin): Top-left corner of the bounding box.(xmax, ymax): Bottom-right corner of the bounding box.
COCO Format
(xmin, ymin, width, height)Similar to Pascal VOC but uses the top-left corner
(xmin, ymin)and absolute width and height instead of bottom-right coordinates.
Absolute Pixel Format
(x, y, width, height)Similar to COCO but without dataset-specific constraints, often used in custom implementations.
Each format has its advantages depending on the dataset, model architecture, and application. Converting between formats is often necessary when working with different object detection models.
Setting Up Your Python Environment
All the code in this guide can be found in my GitHub Repository. Feel free to duplicate and modify for your specific needs.
Before diving into coding, we need to set up our development environment. This will ensure a smooth workflow for processing the dataset, training a Convolutional Neural Network (CNN) for bounding box detection, and evaluating our model.
For this tutorial, we’ll use a Jupyter Notebook, which allows us to execute Python code interactively and visualize data on the fly. This makes debugging and experimentation more efficient.
1. Setting Up Your Project Directory
First, open your terminal (or Command Prompt on Windows) and set up a project folder called CNN_bounding_box_detect, then navigate to it:
mkdir CNN_bounding_box_detect
cd CNN_bounding_box_detect
This ensures all project-related files stay organized in a dedicated directory.
2. Setting Up a Virtual Environment
To keep dependencies isolated and prevent conflicts with other projects, we’ll create a virtual environment:
python -m venv venv Activate the virtual environment:
On Windows:
Bash./venv/Scripts/activateOn macOS/Linux:
Bashsource venv/bin/activate
3. Installing Jupyter Notebook
Once the virtual environment is activated, install Jupyter Notebook:
pip install jupyter Then, launch Jupyter Notebook:
jupyter notebook Now, create a new notebook and name it detect.ipynb. This will be where we write our code for training and testing the CNN model.
4. Installing Dependencies
To train our CNN for bounding box detection, we need several Python libraries. Inside a new cell in detect.ipynb, run:
%pip install numpy pandas matplotlib seaborn tensorflow keras opencv-python tqdm scikit-learnLibrary Breakdown:
tensorflow– Building and training the CNN model.numpy– Handling numerical computations and arrays.pandas– Managing and preprocessing dataset annotations.matplotlib– Visualizing images and training progress.seaborn– Enhancing visualization of training metrics.opencv-python– Image processing (loading, resizing, and bounding box drawing).tqdm– Displaying progress bars for data processing.scikit-learn– Splitting datasets and evaluating model performance.
Once installed, verify the setup by importing the libraries:
import os
import glob
import numpy as np
import pandas as pd
import cv2
import matplotlib.pyplot as plt
import matplotlib.patches as mpatches
import tensorflow as tf
from tensorflow.keras.models import Sequential
from tensorflow.keras.layers import Conv2D, MaxPooling2D, Flatten, Dense, Dropout
from tensorflow.keras.preprocessing.image import ImageDataGenerator
from tensorflow.keras.applications import ResNet50
from tqdm import tqdm
import random
Run the cell. If there are no errors, your environment is successfully set up and libraries installed, and you’re ready to load and process the dataset!
Dataset Overview
In this article, we will work with the Vehicle Number Plate Dataset(Nepal) dataset from Kaggle. This dataset provides a diverse collection of vehicle number plate images captured from various locations across Kathmandu, Bhaktapur, and Lalitpur. It contains 8,078 annotated images.
The images are annotated with bounding boxes that highlight the exact locations of number plates on the vehicles. These annotations make the dataset well-suited for tasks such as license plate recognition, vehicle tracking, and traffic analysis.
Researchers, developers, and enthusiasts can leverage this dataset to train and evaluate algorithms for vehicle identification, as well as explore innovative applications in transportation technology. By using these annotated images, our goal is to train a deep learning model capable of detecting vehicle number plates with high accuracy, contributing to advancements in smart surveillance and automated vehicle recognition systems.
1. Download the Dataset
You can download the Vehicle Number Plate Dataset(Nepal) dataset from Kaggle. Once downloaded, unzip it into a directory called data. You can do so manually or you can use the following commands based on your operating system:
On Windows:
BashExpand-Archive -Path archive.zip -DestinationPath .\dataOn macOS/Linux:
Bashunzip archive.zip -d data
2. Dataset Structure
The Vehicle Number Plate Dataset (Nepal) is organized into the data/vehicle_number_plate_detection directory (or whatever directory you have unzipped your data into), which contains two main subfolders: images and labels.
images: This folder contains the vehicle number plate images in
.jpgformat.labels: This folder contains the annotation files in
.txtformat. Each annotation file corresponds to an image in the images folder and includes bounding box coordinates. These coordinates are normalized values representing the location of the number plates within the images. The annotations are structured in YOLO format, making them suitable for training object detection models.
3. Load and Parse Annotations
Now that we understand the dataset structure and annotation format, we will load and process the annotation files. The goal here is to extract bounding box information from the YOLO-formatted .txt files and store it in a structured format for further use.
We define the dataset paths and implement a function to parse annotation files. Each annotation file contains bounding box details in YOLO format. The parsing function reads these files, extracts the relevant values, and associates them with the corresponding image filenames.
Next, we iterate through all annotation files, extract the bounding box data, and store it in a Pandas DataFrame. This DataFrame will serve as the foundation for visualization and training our deep learning model.
# Define dataset path
DATA_DIR = "data/vehicle_number_plate_detection"
IMAGE_DIR = os.path.join(DATA_DIR, "images")
LABEL_DIR = os.path.join(DATA_DIR, "labels")
IMAGE_EXT = ".jpg"

# Function to parse YOLO annotation files
def parse_yolo_annotation(txt_file):
    with open(txt_file, "r") as file:
        annotations = []
        for line in file:
            parts = line.strip().split()
            label = int(parts[0])  # class label

            # Normalized center coordinates and dimensions
            x_center = float(parts[1])
            y_center = float(parts[2])
            width = float(parts[3])
            height = float(parts[4])

            # Get the image filename (assuming image and annotation share the same basename)
            filename = txt_file.replace(".txt", IMAGE_EXT)

            # Store the normalized values
            annotations.append((filename, x_center, y_center, width, height, label))

    return annotations

# Load all annotations
annotation_files = glob.glob(os.path.join(LABEL_DIR, "*.txt"))
data = []

for txt_file in tqdm(annotation_files, desc="Parsing Annotations"):
    data.extend(parse_yolo_annotation(txt_file))

# Convert to DataFrame
columns = ["filename", "center_x", "center_y", "width", "height", "label"]
df = pd.DataFrame(data, columns=columns)
df.head()
Output: The code should output a pandas DataFrame with the following headers ["filename", "center_x", "center_y", "width", "height", "label"]
4. Visualizing Bounding Boxes
To better understand how these annotations look in practice, it's helpful to visualize the bounding boxes on the images. By doing so, we can verify the accuracy of the annotations and see how the model will be expected to detect number plates.
Here’s a simple way to visualize the bounding boxes using Python and OpenCV:
plt.style.use("dark_background")  # Enable dark mode

def show_sample_images(df, num_samples=6):
    sample_files = df["filename"].unique()
    num_samples = min(num_samples, len(sample_files))  # Adjust if fewer images exist
    selected_files = random.sample(list(sample_files), num_samples)  # Random selection

    num_rows, num_cols = 2, 3  # 2 rows, 3 columns
    fig, axes = plt.subplots(num_rows, num_cols, figsize=(15, 10))
    axes = axes.flatten()  # Flatten for easy iteration

    for i, file in enumerate(selected_files):
        img_path = file.replace("labels", "images")  # Update path if necessary
        img = cv2.imread(img_path)
        img = cv2.cvtColor(img, cv2.COLOR_BGR2RGB)

        sample_data = df[df["filename"] == file]
        for _, row in sample_data.iterrows():
            # Convert from YOLO format to (xmin, ymin, xmax, ymax)
            x_center, y_center, width, height = row["center_x"], row["center_y"], row["width"], row["height"]
            xmin = int((x_center - width / 2) * img.shape[1])
            ymin = int((y_center - height / 2) * img.shape[0])
            xmax = int((x_center + width / 2) * img.shape[1])
            ymax = int((y_center + height / 2) * img.shape[0])

            # Draw bounding box
            cv2.rectangle(img, (xmin, ymin), (xmax, ymax), (0, 255, 0), 4)

        axes[i].imshow(img)
        axes[i].axis("off")
        axes[i].set_title(file, fontsize=10, color="white")

    # Hide unused subplots
    for j in range(i + 1, len(axes)):
        axes[j].axis("off")

    plt.tight_layout()
    plt.savefig("sample_images.png", dpi=300, bbox_inches="tight")
    plt.show()

# Call the function
show_sample_images(df)
This code:
Loads an image and its corresponding annotation file.
Parses the annotation file and converts the normalized bounding box coordinates to pixel values.
Draws a green bounding box around each detected number plate.
Displays the image with bounding boxes for visualization.

This process will help you visually confirm that the bounding boxes are correctly aligned with the Number Plates in the images.
Data Preprocessing and Augmentation
Before training the model, we need to preprocess the images and apply data augmentation to improve the generalization ability of the model. This step includes resizing the images, normalizing pixel values, and applying random transformations like rotation, width/height shifts, zooming, and horizontal flipping.
1. Preprocessing and Data Augmentation
We define the image size and apply preprocessing steps such as normalization and augmentation using ImageDataGenerator from Keras.
# Define image size
IMG_SIZE = (128, 128)

# Data Augmentation and Preprocessing (Combined)
datagen = ImageDataGenerator(
    rescale=1.0 / 255.0,  # Normalize pixel values
    rotation_range=15,    # Random rotations
    width_shift_range=0.2,  # Random horizontal shifts
    height_shift_range=0.2,  # Random vertical shifts
    zoom_range=0.2,      # Random zoom
    horizontal_flip=True,  # Random horizontal flip
    shear_range=0.2,     # Random shear (shearing transformation)
    fill_mode="nearest",  # Filling mode for empty pixels after transformations
)
In the code, we apply both preprocessing and data augmentation techniques in a combined fashion to prepare the data for training. This step helps improve the model's ability to generalize better to unseen data by introducing various transformations that simulate real-world variations.
Rescaling: The
rescale=1.0/255.0parameter normalizes the image pixel values by scaling them to a range between 0 and 1. This is important as neural networks tend to perform better when the input features (such as pixel values) are scaled to a smaller, consistent range.Rotation and Shifting: The
rotation_range=15allows the images to be randomly rotated by up to 15 degrees. This simulates varying orientations of vehicles and number plates. Similarly,width_shift_range=0.2andheight_shift_range=0.2introduce random shifts in the width and height of the images by up to 20%. These transformations help the model become invariant to small shifts in the objects' positions.Zooming and Flipping: The
zoom_range=0.2allows random zooming into the images, which is useful to make the model more robust to variations in object size. Thehorizontal_flip=Truerandomly flips the images horizontally, further enhancing the model's ability to handle different object orientations.Shearing: The
shear_range=0.2introduces a random shear transformation, which simulates slight distortions or perspective changes in the images, making the model more resilient to such variations.
2. Custom Data Generator for Training and Validation
Since the dataset contains both images and bounding boxes, we create a custom data generator that yields batches of images and their corresponding bounding boxes, applying the preprocessing and augmentation steps on the fly.
# Custom generator for images and bounding boxes
def data_generator(df, batch_size=32):
    while True:
        batch_indices = np.random.choice(df.index, batch_size)
        batch_data = df.loc[batch_indices]

        images = []
        bboxes = []

        for _, row in batch_data.iterrows():
            img_path = row["filename"].replace("labels", "images")
            img = cv2.imread(img_path)
            img = cv2.resize(img, IMG_SIZE)

            images.append(img)
            bboxes.append([row["center_x"], row["center_y"], row["width"], row["height"]])

        images = np.array(images, dtype="float32") / 255.0  # Normalize inside generator
        bboxes = np.array(bboxes, dtype="float32")

        yield images, bboxes
The data_generator function:
Randomly selects a batch of images and corresponding bounding boxes from the dataset.
Resizes the images to the specified size and normalizes them.
Yields the images and their associated bounding box coordinates for use in training.
3. Training and Validation Generators
Finally, we define two generators: one for training data and one for validation data. The training generator will apply the augmentations, and the validation generator will provide a consistent set of data for evaluating the model.
# Define training and validation generators
batch_size = 32
train_generator = data_generator(df.sample(frac=0.8, random_state=42), batch_size=batch_size)
val_generator = data_generator(df.drop(df.sample(frac=0.8, random_state=42).index), batch_size=batch_size) train_generatorwill provide augmented training data.val_generatorwill handle the validation data without augmentation to maintain consistency during evaluation.
With this setup, the model will train using real-time data augmentation, enhancing its ability to recognize number plates in a variety of conditions.
Model Architecture
1. Loss Function and IoU Metric
For this object detection task, we use Mean Squared Error (MSE) as the loss function to optimize the model’s bounding box predictions. MSE is commonly used for regression tasks, making it useful for learning the four bounding box coordinates:
(xcenter, ycenter, width, height)
MSE minimizes the squared differences between the predicted and true bounding box values, helping the model learn precise localization.
IoU as an Evaluation Metric
Although we are optimizing with MSE, we also track the Intersection over Union (IoU) as a metric to measure prediction accuracy.
What is IoU? IoU is a measure of how well the predicted bounding box overlaps with the ground truth bounding box. It is defined as:
IoU = Intersection Area / Union Area
Where:
Intersection Area is the overlap between the predicted and ground truth boxes
Union Area is the total area covered by both boxes
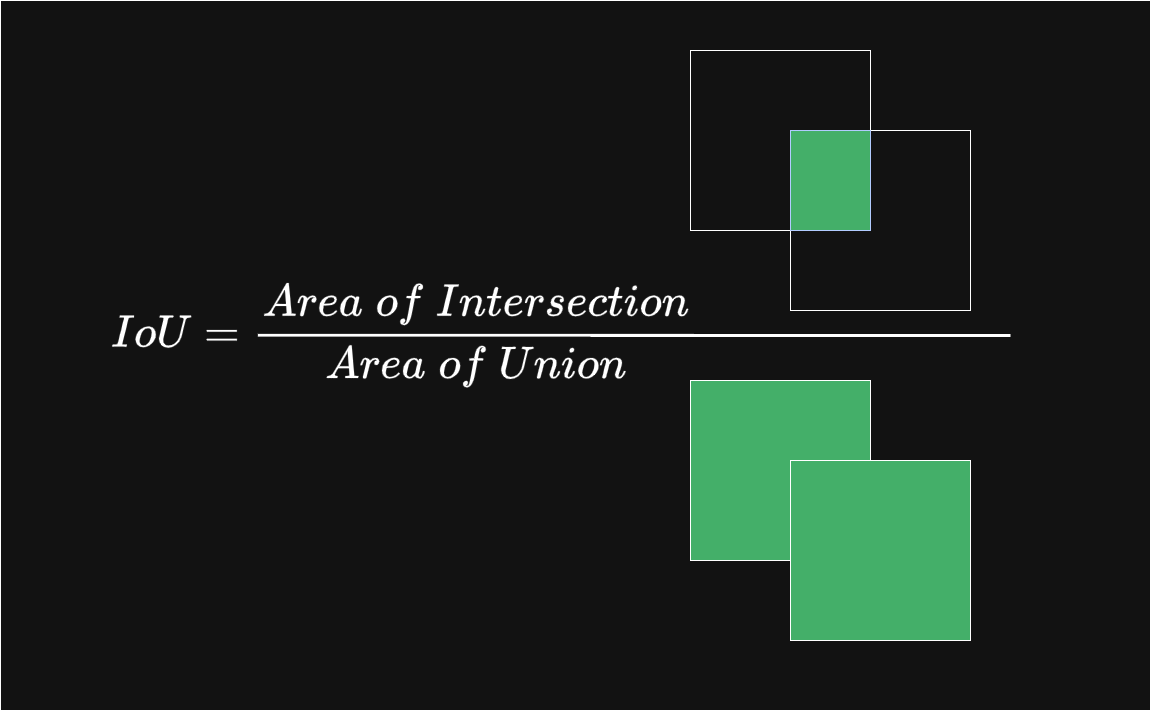
A higher IoU means a better prediction. We track IoU to ensure that our model is producing boxes that closely match the ground truth.
Here’s how we define the IoU metric in our model:
def iou_loss(y_true, y_pred):
    # Cast y_true to float32 to match the type of y_pred
    y_true = tf.cast(y_true, tf.float32)

    # Extract ground truth and predicted coordinates in center_x, center_y, width, height form
    center_x_true, center_y_true, width_true, height_true = tf.split(y_true, 4, axis=-1)
    center_x_pred, center_y_pred, width_pred, height_pred = tf.split(y_pred, 4, axis=-1)

    # Convert center_x, center_y, width, height to xmin, ymin, xmax, ymax
    xmin_true = center_x_true - width_true / 2
    ymin_true = center_y_true - height_true / 2
    xmax_true = center_x_true + width_true / 2
    ymax_true = center_y_true + height_true / 2

    xmin_pred = center_x_pred - width_pred / 2
    ymin_pred = center_y_pred - height_pred / 2
    xmax_pred = center_x_pred + width_pred / 2
    ymax_pred = center_y_pred + height_pred / 2

    # Calculate intersection area
    inter_x1 = tf.maximum(xmin_true, xmin_pred)
    inter_y1 = tf.maximum(ymin_true, ymin_pred)
    inter_x2 = tf.minimum(xmax_true, xmax_pred)
    inter_y2 = tf.minimum(ymax_true, ymax_pred)

    inter_area = tf.maximum(inter_x2 - inter_x1, 0) * tf.maximum(inter_y2 - inter_y1, 0)

    # Calculate union area
    true_area = (xmax_true - xmin_true) * (ymax_true - ymin_true)
    pred_area = (xmax_pred - xmin_pred) * (ymax_pred - ymin_pred)

    union_area = true_area + pred_area - inter_area

    # IoU is the intersection area divided by union area
    iou = inter_area / (union_area + tf.keras.backend.epsilon())

    # Return 1 - IoU as loss (lower IoU means higher loss)
    return 1 - iou
2. Model Architecture
In our model, we will define a sequence of convolutional layers followed by max-pooling layers to extract features from the input images. After extracting these features, we will flatten the output and pass it through a few fully connected layers, ultimately predicting the bounding box coordinates for the object.
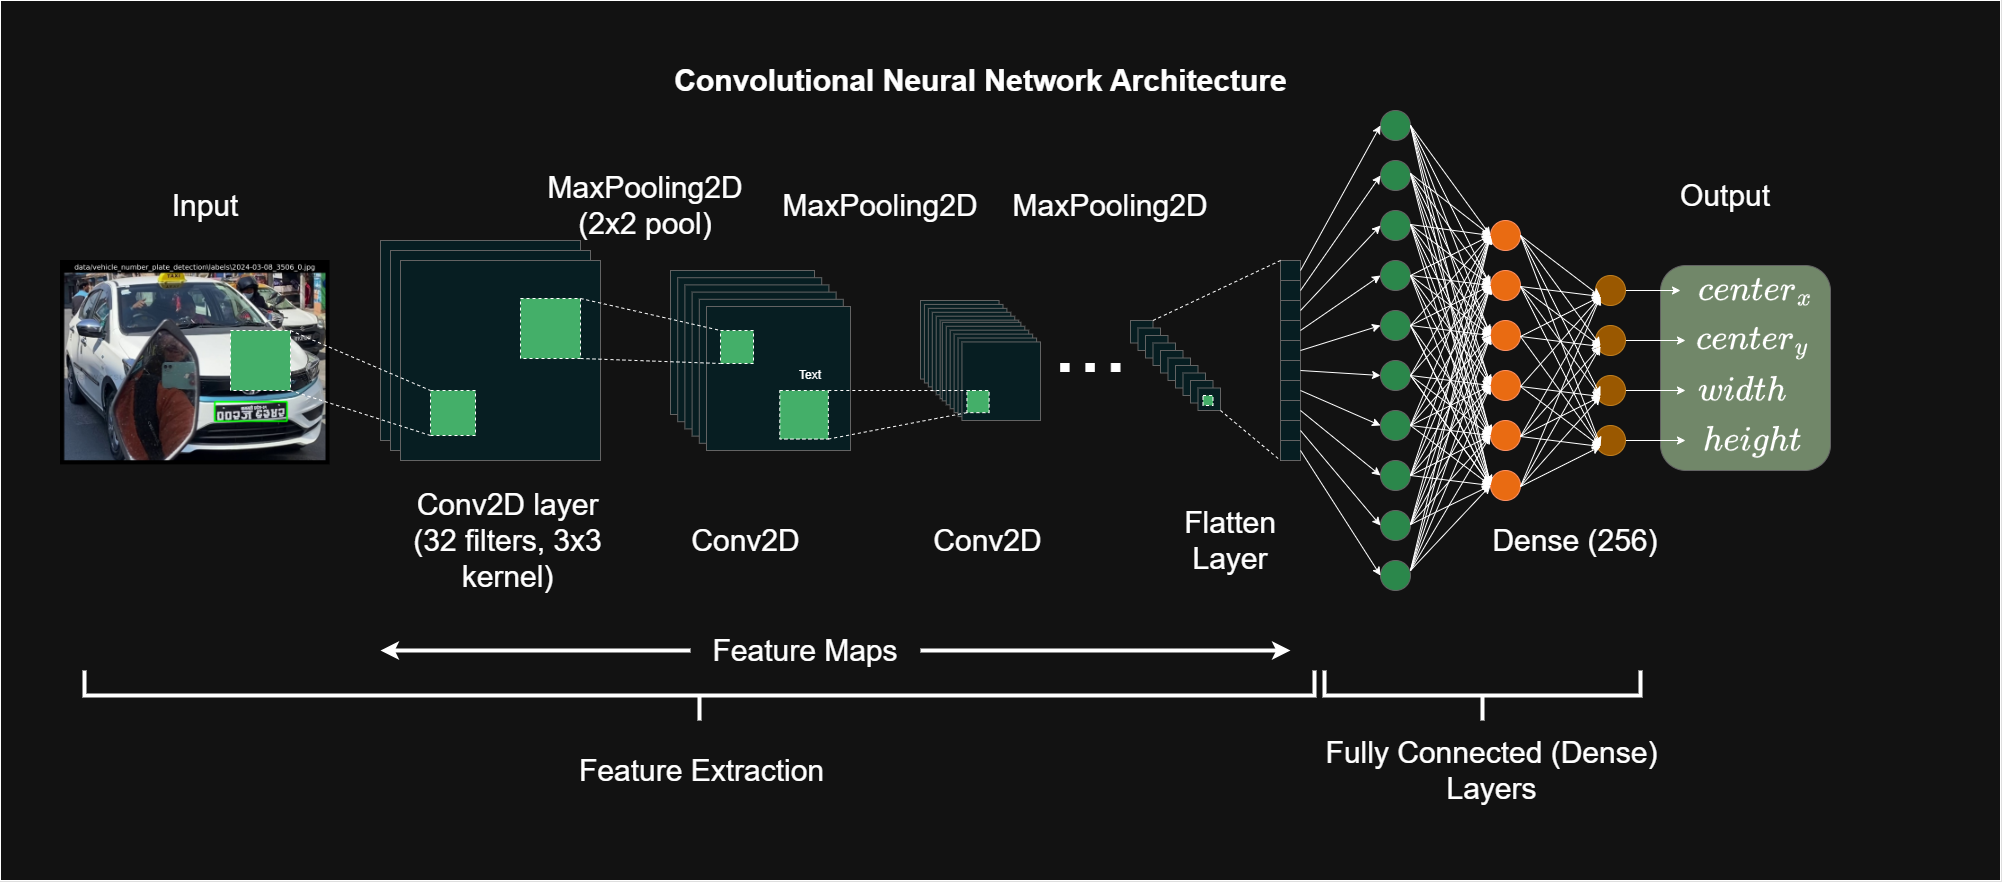
Here is the architecture of the model:
model = Sequential([
    Conv2D(32, (3, 3), activation="relu", input_shape=(128, 128, 3)),
    MaxPooling2D(2, 2),
    Conv2D(64, (3, 3), activation="relu"),
    MaxPooling2D(2, 2),
    Conv2D(128, (3, 3), activation="relu"),
    MaxPooling2D(2, 2),
    Flatten(),
    Dense(256, activation="relu"),
    Dense(4, activation="sigmoid")  # Bounding box output (center_x, center_y, width, height)
])

model.compile(optimizer="adam", loss="mse", metrics=["mae", iou_loss])
model.summary()
3. Explaining the Architecture
Convolutional Layers (Conv2D): These layers are responsible for detecting patterns in the image, such as edges, shapes, and textures. The number of filters (32, 64, 128) increases as we go deeper into the network, allowing the model to learn increasingly complex features.
MaxPooling Layers (MaxPooling2D): These layers reduce the spatial dimensions of the feature maps, which helps to speed up computation and reduce overfitting. The pooling operation also makes the model more invariant to small translations of the objects.
Flatten Layer: After feature extraction, the output is flattened into a 1D vector so that it can be passed to the fully connected layers for further processing.
Dense Layers: These fully connected layers allow the model to combine the features extracted by the convolutional layers and make predictions. The last dense layer outputs 4 values corresponding to the bounding box coordinates:
(center_x, center_y, width, height).
If you want to understand more about how CNNs work, check out Feature Extraction and Convolutional Neural Networks.
Model Training
Now that we have defined our model architecture and chosen an appropriate loss function, it's time to train the model. Training involves feeding images through the model, computing the loss between the predicted and actual bounding boxes, and updating the model's parameters using backpropagation to minimize this loss.
Instead of loading all the data into memory at once, we use the custom data generator to efficiently stream the training images and their corresponding bounding boxes in batches. This is especially useful when working with large datasets, as it prevents memory overload and allows for efficient training. The training process follows these steps:
Forward Pass: The input images are passed through the convolutional layers to extract features, followed by fully connected layers that output the predicted bounding boxes.
Loss Computation: The model computes the difference between the predicted bounding boxes and the actual ground truth boxes using the Mean Squared Error (MSE) loss.
Backward Pass (Gradient Update): The optimizer adjusts the model’s weights to minimize the loss, helping the model make more accurate predictions over time.
Validation: After each epoch, the model's performance is evaluated on a separate validation set to monitor progress and detect overfitting.
We set up the training process with 100 epochs and a batch size of 32, meaning that the model will see the entire dataset 100 times, with updates happening in batches of 32 images at a time.
EPOCHS = 100
BATCH_SIZE = 32

# Train the model using the custom data generator
history = model.fit(
    train_generator,  # Use the custom generator for training data
    steps_per_epoch=len(df.sample(frac=0.8, random_state=42)) // BATCH_SIZE,  # Number of batches per epoch
    validation_data=val_generator,  # Validation data generator
    validation_steps=len(df.drop(df.sample(frac=0.8, random_state=42).index)) // BATCH_SIZE,  # Number of validation batches
    epochs=EPOCHS,
    verbose=1
)

# Save the trained model for later use
model.save("plate_detection_model.h5")  # Saves in HDF5 format
Saving the Model
After training is complete, we save the model in HDF5 format (.h5). This allows us to reload and use the trained model later without retraining from scratch. We can use this saved model to make predictions on new images or fine-tune it further if needed.
By the end of training, our model should have learned to accurately predict bounding boxes for objects in the dataset. In the next step, we will evaluate the model’s performance and visualize its predictions.
Evaluating the Model
After training, we need to evaluate the model to understand how well it has learned to predict bounding boxes. We will assess the model using the following metrics:
Mean Absolute Error (MAE): Measures the average absolute difference between predicted and actual bounding box coordinates.
Mean Squared Error (MSE): Penalizes larger errors more than MAE by squaring the differences. This was the loss function used during training.
Mean Intersection over Union (IoU): A metric for object detection that quantifies how well the predicted bounding box overlaps with the ground truth box. A higher IoU value indicates better performance.
Additionally, we will visualize:
The loss curves for training and validation to check for convergence and possible overfitting.
A few sample predictions to see how well the model is performing on individual images.
1. Evaluate the Model on the Validation Set
We use the .evaluate() method to compute the final loss and metrics on the validation dataset.
# Evaluate the model on the validation set
val_loss, val_mae, val_iou = model.evaluate(val_generator, verbose=1)

print(f"Validation Loss (MSE): {val_loss:.4f}")
print(f"Validation Mean Absolute Error (MAE): {val_mae:.4f}")
print(f"Validation Mean IoU: {1 - val_iou:.4f}")  # Since our IoU loss is 1 - IoU
Output:
Validation Loss (MSE): 0.0134
Validation Mean Absolute Error (MAE): 0.0541
Validation Mean IoU: 0.3862
The model's performance on the validation set provides insight into its ability to predict bounding boxes accurately:
Validation Loss (MSE) = 0.0134
A low MSE indicates that the predicted bounding box coordinates are numerically close to the ground truth values.
However, since MSE primarily measures squared differences, it does not directly reflect how well the bounding boxes overlap.
Validation Mean Absolute Error (MAE) = 0.0541
The MAE value shows that, on average, the predicted bounding box coordinates deviate by approximately 5.41% of the image dimensions from the actual values.
This suggests that the model is relatively precise in predicting box coordinates but may still have room for improvement.
Validation Mean IoU = 0.3862
The Intersection over Union (IoU) score measures how well the predicted bounding box overlaps with the ground truth.
A mean IoU of 0.3862 indicates that, on average, only 38.62% of the predicted bounding box overlaps with the actual object.
In object detection, an IoU of at least 0.5 is generally considered acceptable, with values above 0.75 being ideal for high-accuracy models.
2. Plot Training and Validation Loss
Visualizing the training process helps us understand whether the model is learning properly.
# Extract loss and validation loss from the history object
plt.figure(figsize=(10, 5))
plt.plot(history.history["loss"], label="Training Loss (MSE)", color="blue")
plt.plot(history.history["val_loss"], label="Validation Loss (MSE)", color="orange")
plt.xlabel("Epochs")
plt.ylabel("Loss")
plt.title("Training vs Validation Loss")
plt.legend()
plt.grid()
plt.savefig("training_loss.png", dpi=300, bbox_inches="tight")
plt.show()
3. Visualize Training and Validation MAE
plt.figure(figsize=(10, 5))
plt.plot(history.history["mae"], label="Training MAE", color="blue")
plt.plot(history.history["val_mae"], label="Validation MAE", color="orange")
plt.xlabel("Epochs")
plt.ylabel("Mean Absolute Error")
plt.title("Training vs Validation MAE")
plt.legend()
plt.grid()
plt.savefig("training_mae.png", dpi=300, bbox_inches="tight")
plt.show()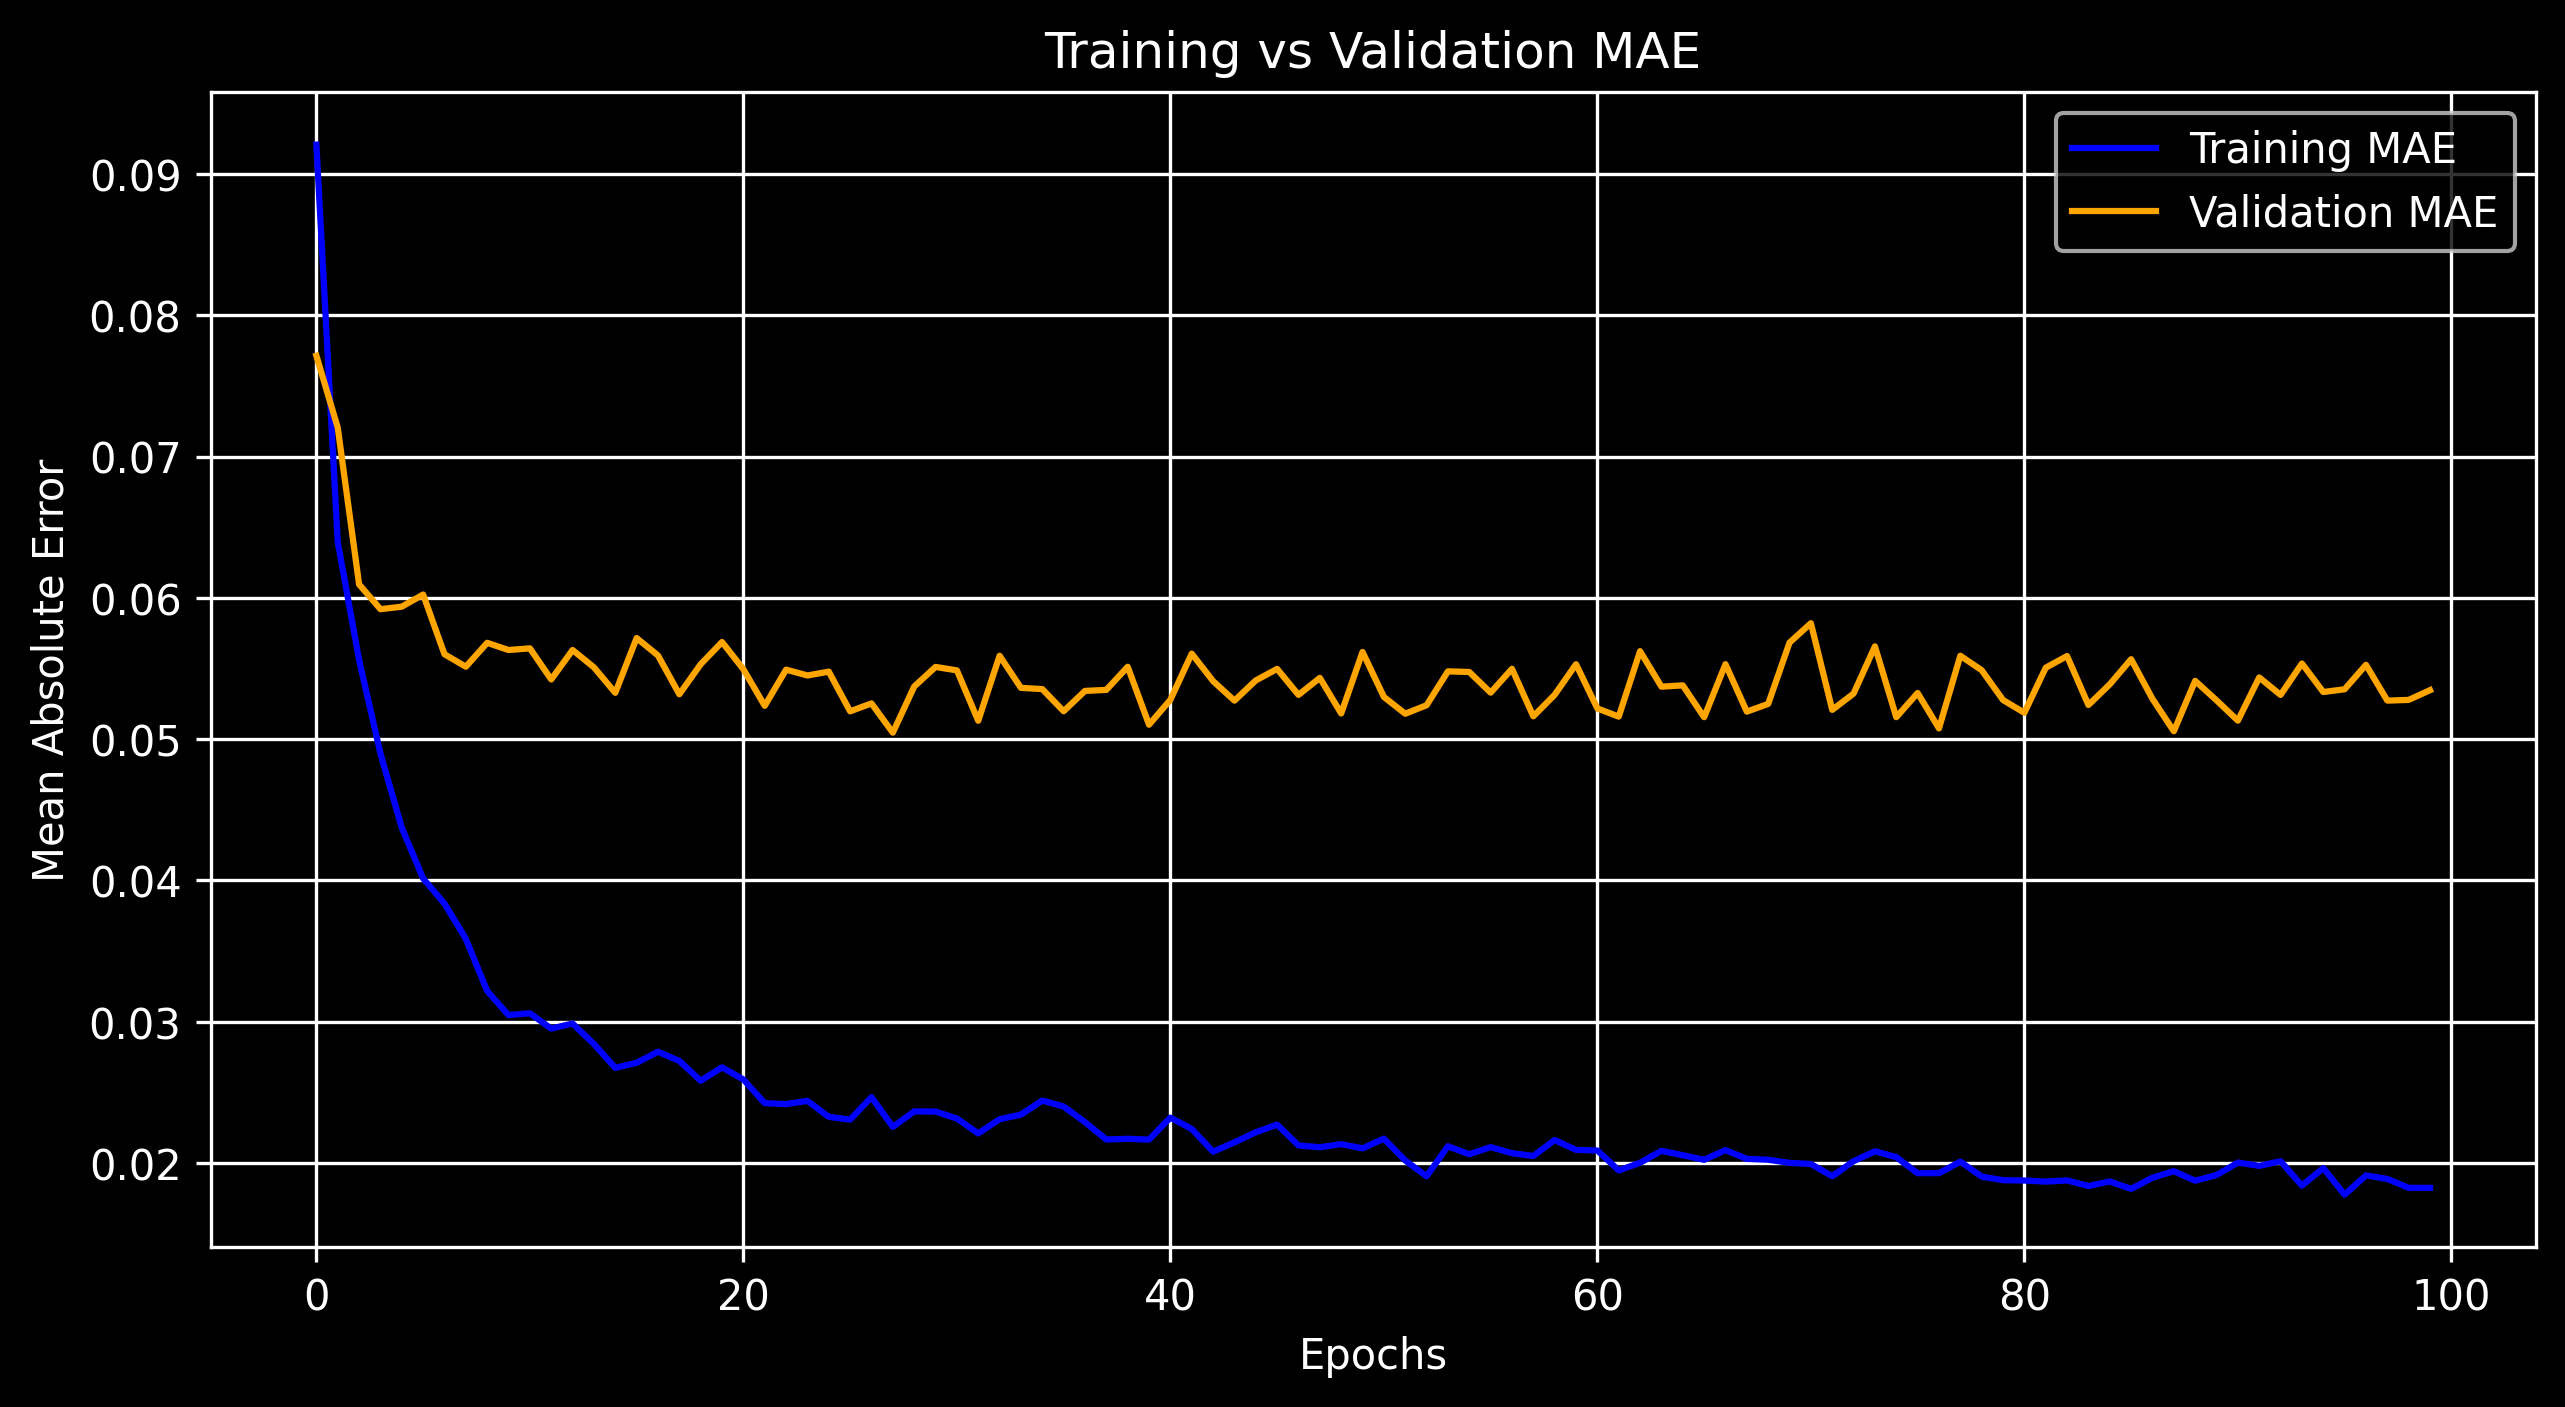
4. Visualize Mean IoU During Training
plt.figure(figsize=(10, 5))
plt.plot([1 - iou for iou in history.history["iou_loss"]], label="Training IoU", color="blue")
plt.plot([1 - iou for iou in history.history["val_iou_loss"]], label="Validation IoU", color="orange")
plt.xlabel("Epochs")
plt.ylabel("Mean IoU")
plt.title("Training vs Validation IoU")
plt.legend()
plt.grid()
plt.savefig("training_iou.png", dpi=300, bbox_inches="tight")
plt.show() 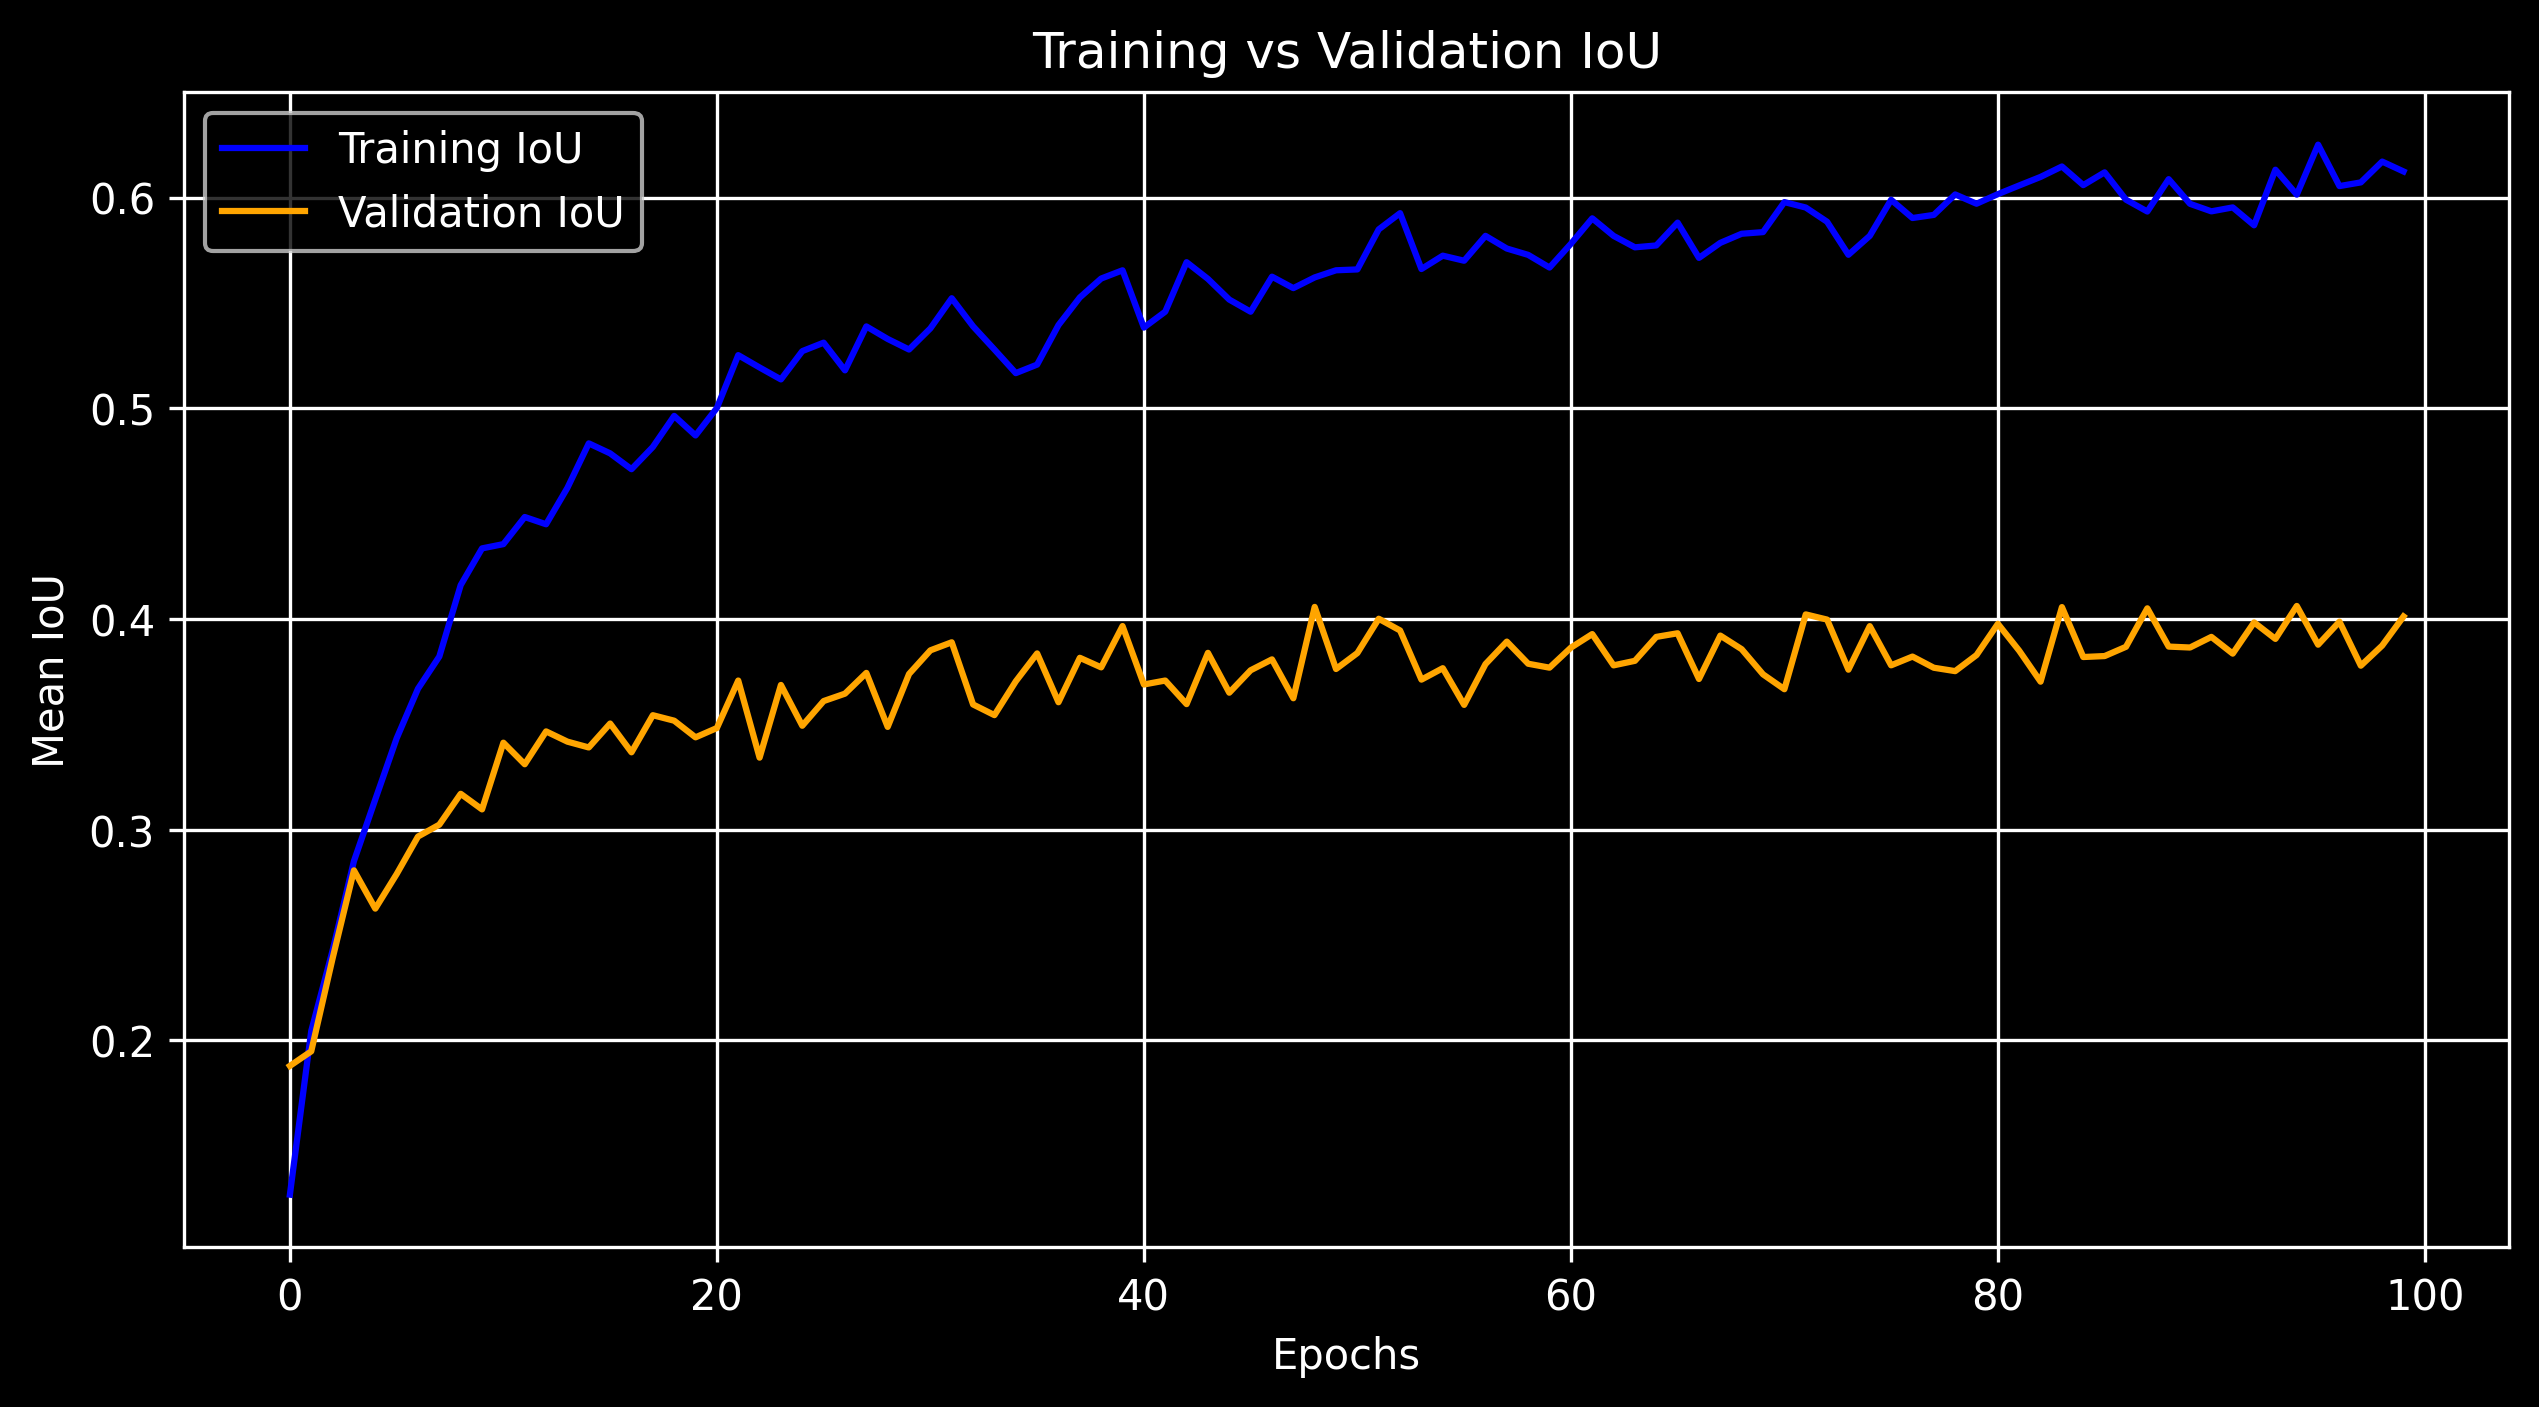
5. Visualize Predictions on Sample Images
def visualize_predictions(model, data_generator, num_samples=6, save_path="predictions.png"):
    # Get a single batch from the generator
    X_batch, y_batch = next(data_generator)

    # Select random indices from the batch
    random_indices = random.sample(range(len(X_batch)), num_samples)

    # Predict bounding boxes for the selected samples
    preds = model.predict(X_batch[random_indices])

    fig, axes = plt.subplots(2, 3, figsize=(15, 10))  # 2x3 grid

    for i, idx in enumerate(random_indices):
        img = (X_batch[idx] * 255).astype("uint8")

        # True bounding box (convert from center format to (xmin, ymin, xmax, ymax))
        true_x_center, true_y_center, true_width, true_height = y_batch[idx]
        true_xmin = int((true_x_center - true_width / 2) * IMG_SIZE[0])
        true_ymin = int((true_y_center - true_height / 2) * IMG_SIZE[1])
        true_xmax = int((true_x_center + true_width / 2) * IMG_SIZE[0])
        true_ymax = int((true_y_center + true_height / 2) * IMG_SIZE[1])

        # Predicted bounding box
        pred_x_center, pred_y_center, pred_width, pred_height = preds[i]
        pred_xmin = int((pred_x_center - pred_width / 2) * IMG_SIZE[0])
        pred_ymin = int((pred_y_center - pred_height / 2) * IMG_SIZE[1])
        pred_xmax = int((pred_x_center + pred_width / 2) * IMG_SIZE[0])
        pred_ymax = int((pred_y_center + pred_height / 2) * IMG_SIZE[1])

        # Draw bounding boxes (green for true, red for predicted)
        cv2.rectangle(img, (true_xmin, true_ymin), (true_xmax, true_ymax), (0, 255, 0), 2)  # True bbox in green
        cv2.rectangle(img, (pred_xmin, pred_ymin), (pred_xmax, pred_ymax), (255, 0, 0), 2)  # Pred bbox in red

        # Place image in correct subplot
        ax = axes[i // 3, i % 3]
        ax.imshow(img)
        ax.axis("off")
        ax.set_title(f"Sample {idx+1}")

    # Add legend
    green_patch = mpatches.Patch(color='green', label='True Bounding Box')
    red_patch = mpatches.Patch(color='red', label='Predicted Bounding Box')
    fig.legend(handles=[green_patch, red_patch], loc="upper center", fontsize=12)

    # Save the figure
    plt.savefig(save_path, bbox_inches="tight", dpi=300)

    # Show the figure
    plt.show()

# Call the function to visualize predictions and save the image
visualize_predictions(model, train_generator, save_path="bbox_predictions.png")
Analysis & Potential Improvements
The relatively low IoU suggests that while the model's coordinate predictions are numerically close, they do not always lead to well-aligned bounding boxes. Some possible improvements include:
Enhancing the dataset: Increasing the number of training samples and applying data augmentation (e.g., flipping, rotation, brightness adjustments) can help the model generalize better.
Refining the loss function: Instead of using MSE alone, incorporating a direct IoU-based loss or a combination of losses (e.g., smooth L1 loss) could improve bounding box alignment.
Tuning hyperparameters: Adjusting learning rate, batch size, and optimizer settings might lead to better convergence.
Using a more complex model: The current CNN-based approach might be too simple. Exploring architectures like YOLO, Faster R-CNN, or RetinaNet could yield better performance.
While the model is making reasonable predictions, improving IoU should be a key focus to enhance the overall accuracy of the bounding box detection.
Conclusion and Next Steps
In this article, we successfully built an object detection model for vehicle number plate detection using a custom CNN architecture. We started by understanding the dataset, preprocessing images and labels, and defining a YOLO-format compatible bounding box system. We then built and trained our model using Mean Squared Error (MSE) loss with MAE and IoU as evaluation metrics. Finally, we evaluated the model's performance through numerical metrics and visualizations.
Key Takeaways:
We prepared and preprocessed a dataset of labeled vehicle number plates.
We designed and trained a CNN-based model to predict bounding boxes around number plates.
We evaluated the model using MSE, MAE, and IoU metrics and visualized results.
We identified potential improvements for better accuracy.
Next Steps:
While our model is functional, there are several ways to enhance its performance:
Fine-tune the model by adjusting hyperparameters like learning rate, batch size, and optimizer settings.
Use a deeper architecture such as YOLO, Faster R-CNN, or EfficientDet, which are state-of-the-art object detection models.
Augment the dataset with brightness changes, rotations, and synthetic images to improve generalization.
Train on a larger dataset with diverse vehicle images from different angles, lighting conditions, and resolutions.
Deploy the model into a real-world application, such as an automatic license plate recognition (ALPR) system using OpenCV and Tesseract OCR for character recognition.
By following these steps, we can refine our model into a more accurate and robust number plate detection system, paving the way for real-world applications in traffic monitoring, security, and automated toll systems.
All the code in this guide can be found in my GitHub Repository. Feel free to duplicate and modify for your specific needs.
Read More
Read more articles on the topics that interest you
Solar Cost for Small Businesses in South Africa: Ranges
See what different system sizes include, where extra costs hide, and how to compare quotes
How to Buy Bitcoin in South Africa Legally in 5 Steps
Choose a provider, pay in rand, check the costs and keep tax records
How to Build a Full-Stack Web App With AI in 7 Steps
Adapt a starter project, then use AI to build, test and launch your first working version
Best AI Website Builders for Beginners in 2026: 5 Picks
Compare easy site creation, online selling, costs and the trade-offs before you choose
6 Ways South African Youth Can Fight AI Unemployment
Build skills employers need, earn while learning and make AI work alongside you
Jobs most likely to be replaced by Artificial Intelligence
Exploring careers at risk due to AI advancements and automation